diff --git a/CNAME b/CNAME
deleted file mode 100644
index 0ee23f83..00000000
--- a/CNAME
+++ /dev/null
@@ -1 +0,0 @@
-docs.cellxgene.cziscience.com
diff --git a/CONTRIBUTING.md b/CONTRIBUTING.md
index fbbc0f1e..64cf2451 100644
--- a/CONTRIBUTING.md
+++ b/CONTRIBUTING.md
@@ -1,3 +1,3 @@
We warmly welcome contributions from the community!
-Whether you want to contribute ideas, requests, documentation, or code, you can get started by visiting our [contribution guide](https://chanzuckerberg.github.io/cellxgene/posts/contribute).
+Whether you want to contribute ideas, requests, documentation, or code, you can get started by visiting our [contribution guide](https://github.com/chanzuckerberg/cellxgene-documentation/blob/main/contribute.md).
diff --git a/README.md b/README.md
index f6225fd3..15c99a0f 100644
--- a/README.md
+++ b/README.md
@@ -7,27 +7,27 @@ _an interactive explorer for single-cell transcriptomics data_
[](https://github.com/chanzuckerberg/cellxgene/actions?query=workflow%3A%22Compatibility+Tests%22)

-cellxgene (pronounced "cell-by-gene") is an interactive data explorer for single-cell transcriptomics datasets, such as those coming from the [Human Cell Atlas](https://humancellatlas.org). Leveraging modern web development techniques to enable fast visualizations of at least 1 million cells, we hope to enable biologists and computational researchers to explore their data.
+cellxgene Desktop (pronounced "cell-by-gene") is an interactive data explorer for single-cell datasets, such as those coming from the [Human Cell Atlas](https://humancellatlas.org). Leveraging modern web development techniques to enable fast visualizations of at least 1 million cells, we hope to enable biologists and computational researchers to explore their data.
-Whether you need to visualize one thousand cells or one million, cellxgene helps you gain insight into your single-cell data.
+Whether you need to visualize one thousand cells or one million, cellxgene Desktop helps you gain insight into your single-cell data.

# Getting started
-### The comprehensive guide to cellxgene
+### The comprehensive guide to cellxgene Desktop
-[The cellxgene documentation is your one-stop-shop for information about cellxgene](https://chanzuckerberg.github.io/cellxgene/)! You may be particularly interested in:
+[The cellxgene documentation is your one-stop-shop for information about cellxgene Desktop](https://github.com/chanzuckerberg/cellxgene-documentation/blob/main/README.md)! You may be particularly interested in:
-- Seeing [what cellxgene can do](https://chanzuckerberg.github.io/cellxgene/posts/gallery)
-- Learning more about cellxgene [installation](https://chanzuckerberg.github.io/cellxgene/posts/install) and [usage](https://chanzuckerberg.github.io/cellxgene/posts/launch)
-- [Preparing your own data](https://chanzuckerberg.github.io/cellxgene/posts/prepare) for use in cellxgene
-- Checking out [our roadmap](https://chanzuckerberg.github.io/cellxgene/posts/roadmap) for future development
-- [Contributing](https://chanzuckerberg.github.io/cellxgene/posts/contribute) to cellxgene
+- Seeing [what cellxgene Desktop can do](https://github.com/chanzuckerberg/cellxgene-documentation/blob/main/explore-data/explorer-tutorials.md)
+- Learning more about cellxgene [installation](https://github.com/chanzuckerberg/cellxgene-documentation/blob/main/desktop/install.md) and [usage](https://github.com/chanzuckerberg/cellxgene-documentation/blob/main/desktop/quick-start.md#quick-start-1)
+- [Preparing your own data](https://github.com/chanzuckerberg/cellxgene-documentation/blob/main/desktop/data-reqs.md) for use in cellxgene Desktop
+- Checking out [our roadmap](https://github.com/chanzuckerberg/cellxgene-documentation/blob/main/roadmap.md) for future development
+- [Contributing](https://github.com/chanzuckerberg/cellxgene-documentation/blob/main/contribute.md) to cellxgene Desktop
### Quick start
-To install cellxgene you need Python 3.6+. We recommend [installing cellxgene into a conda or virtual environment.](https://chanzuckerberg.github.io/cellxgene/posts/install)
+To install cellxgene Desktop you need Python 3.6+. We recommend [installing cellxgene Desktop into a conda or virtual environment.](https://github.com/chanzuckerberg/cellxgene-documentation/blob/main/desktop/install.md)
Install the package.
@@ -35,19 +35,19 @@ Install the package.
pip install cellxgene
```
-Launch cellxgene with an example [anndata](https://anndata.readthedocs.io/en/latest/) file
+Launch cellxgene Desktop with an example [anndata](https://anndata.readthedocs.io/en/latest/) file
```bash
cellxgene launch https://cellxgene-example-data.czi.technology/pbmc3k.h5ad
```
-To explore more datasets already formatted for cellxgene, check out the [Demo data](https://chanzuckerberg.github.io/cellxgene/posts/demo-data) or
-see [Preparing your data](https://chanzuckerberg.github.io/cellxgene/posts/prepare) to learn more about formatting your own
-data for cellxgene.
+To explore more datasets already formatted for cellxgene Desktop, check out the [Demo data](https://github.com/chanzuckerberg/cellxgene-documentation/blob/main/desktop/quick-start.md#example-datasets) or
+see [Preparing your data](https://github.com/chanzuckerberg/cellxgene-documentation/blob/main/desktop/data-reqs.md) to learn more about formatting your own
+data for cellxgene Desktop.
### Supported browsers
-cellxgene currently supports the following browsers:
+cellxgene Desktop currently supports the following browsers:
- Google Chrome 61+
- Edge 15+
@@ -62,11 +62,11 @@ For questions, suggestions, or accolades, [join the `#cellxgene-users` channel o
For any errors, [report bugs on Github](https://github.com/chanzuckerberg/cellxgene/issues).
-# Developing with cellxgene
+# Developing with cellxgene Desktop
### Contributing
-We warmly welcome contributions from the community! Please see our [contributing guide](https://chanzuckerberg.github.io/cellxgene/posts/contribute) and don't hesitate to open an issue or send a pull request to improve cellxgene. Please see the [dev_docs](https://github.com/chanzuckerberg/cellxgene/tree/main/dev_docs) for pull request suggestions, unit test details, local documentation preview, and other development specifics.
+We warmly welcome contributions from the community! Please see our [contributing guide](https://github.com/chanzuckerberg/cellxgene-documentation/blob/main/contribute.md) and don't hesitate to open an issue or send a pull request to improve cellxgene Desktop. Please see the [dev_docs](https://github.com/chanzuckerberg/cellxgene/tree/main/dev_docs) for pull request suggestions, unit test details, local documentation preview, and other development specifics.
This project adheres to the Contributor Covenant [code of conduct](https://github.com/chanzuckerberg/.github/blob/master/CODE_OF_CONDUCT.md). By participating, you are expected to uphold this code. Please report unacceptable behavior to opensource@chanzuckerberg.com.
@@ -79,9 +79,9 @@ this project. All code is freely available for reuse under the [MIT license](htt
Before extending cellxgene, we encourage you to reach out to us with ideas or questions. It might be possible that an
extension could be directly contributed, which would make it available for a wider audience, or that it's on our
-[roadmap](./docs/posts/roadmap.md) and under active development.
+[roadmap](https://github.com/chanzuckerberg/cellxgene-documentation/blob/main/roadmap.md) and under active development.
-See the [cellxgene extensions](./docs/posts/extensions.md) section of our documentation for examples of community use and cellxgene extensions.
+See the [cellxgene extensions](https://github.com/chanzuckerberg/cellxgene-documentation/blob/main/community-extensions.md) section of our documentation for examples of community use and cellxgene extensions.
### Security
diff --git a/dev_docs/developer_guidelines.md b/dev_docs/developer_guidelines.md
index f72929b6..33e918d8 100644
--- a/dev_docs/developer_guidelines.md
+++ b/dev_docs/developer_guidelines.md
@@ -150,19 +150,4 @@ If you would like to run the smoke tests against a hot-reloaded version of the c
- You can also install/launch the server side code from npm scrips (requires python3.6 with virtualenv) with the `scripts/backend_dev` script.
-- Check out [e2e Tests](e2e_tests.md) for more details
-
-## Doc changes
-
-To evaluate changes to documentation in `cellxgene/docs`, you must install [jekyll](https://jekyllrb.com/docs/installation/), then run:
-
-```bash
-cd docs
-bundle install
-bundle exec jekyll serve
-```
-
-If changes look good, run the following, then commit and push:
-```bash
-bundle exec jekyll build
-```
+- Check out [e2e Tests](e2e_tests.md) for more details
\ No newline at end of file
diff --git a/docs/Gemfile b/docs/Gemfile
deleted file mode 100644
index a6011a22..00000000
--- a/docs/Gemfile
+++ /dev/null
@@ -1,3 +0,0 @@
-source 'https://rubygems.org'
-gem "github-pages", group: :jekyll_plugins
-gem 'jekyll-relative-links'
diff --git a/docs/_config.yml b/docs/_config.yml
deleted file mode 100644
index 4290ac5f..00000000
--- a/docs/_config.yml
+++ /dev/null
@@ -1,39 +0,0 @@
-theme: jekyll-theme-minimal
-show_downloads: false
-url: "https://chanzuckerberg.github.io"
-baseurl: "/cellxgene"
-
-plugins:
- - jekyll-relative-links
-
-logo: cellxgene-logo.png
-
-nav:
- - title: Installation
- url: posts/install
- - title: Gallery
- url: posts/gallery
- - title: Cellxgene data portal
- url: https://cellxgene.cziscience.com/
- - title: Demo datasets
- url: posts/demo-data
- - title: Preparing your data
- url: posts/prepare
- - title: Launching cellxgene
- url: posts/launch
- - title: Hosting cellxgene
- url: posts/hosted
- - title: Annotating data
- url: posts/annotations
- - title: Methods
- url: posts/methods
- - title: Troubleshooting
- url: posts/troubleshooting
- - title: Roadmap
- url: posts/roadmap
- - title: Contributing (ideas or code)
- url: posts/contribute
- - title: Extensions
- url: posts/extensions
- - title: Contact & finding help
- url: posts/contact
diff --git a/docs/_layouts/default.html b/docs/_layouts/default.html
deleted file mode 100644
index c68a09fb..00000000
--- a/docs/_layouts/default.html
+++ /dev/null
@@ -1,61 +0,0 @@
-
-
-
{{ site.description | default: site.github.project_tagline }}
-
-
- {% if page.url == "/" %}
- Quick start
- {% else %}
- Quick start
- {% endif %}
-
- {% for item in site.nav %}
- {% if page.url contains item.url %}
- {{ item.title }}
- {% else %}
- {{ item.title }}
- {% endif %}
- {% endfor %}
-
- Code
-
-
- An interactive explorer for single-cell transcriptomics data
-
-
-
- Quick start
-
-
-
-
- Installation
-
-
-
- Gallery
-
-
-
- Demo datasets
-
-
-
- All other datasets
-
-
-
- Preparing your data
-
-
-
- Launching cellxgene
-
-
-
- Hosting cellxgene
-
-
-
- Annotating data
-
-
-
- Methods
-
-
-
- Troubleshooting
-
-
-
- Roadmap
-
-
-
- Contributing (ideas or code)
-
-
-
- Extensions
-
-
-
- Contact & finding help
-
-
-
- Code
-
Chan Zuckerberg has an online repository of public single-cell datasets for exploration with cellxgene.
- -If you have a public dataset which you would like hosted for visualization on this site, -with a link to embed on your own site, please drop us a note at cellxgene@chanzuckerberg.com.
- -
-
- An interactive explorer for single-cell transcriptomics data
-
-
-
- Quick start
-
-
-
-
- Installation
-
-
-
- Gallery
-
-
-
- Cellxgene data portal
-
-
-
- Demo datasets
-
-
-
- Preparing your data
-
-
-
- Launching cellxgene
-
-
-
- Hosting cellxgene
-
-
-
- Annotating data
-
-
-
- Methods
-
-
-
- Troubleshooting
-
-
-
- Roadmap
-
-
-
- Contributing (ideas or code)
-
-
-
- Extensions
-
-
-
- Contact & finding help
-
-
-
- Code
-
Whether you need to visualize one thousand cells or one million, cellxgene helps you gain insight into your single-cell data.
- -To install cellxgene you need Python 3.6+. We recommend installing cellxgene into a conda or virtual environment.
- -Install the package.
-pip install cellxgene
-Launch cellxgene with an example anndata file
- -cellxgene launch https://cellxgene-example-data.czi.technology/pbmc3k.h5ad
-To explore more datasets already formatted for cellxgene, check out the Demo data or -see Preparing your data to learn more about formatting your own -data for cellxgene.
- -We’d love to hear from you!
- -For questions, suggestions, or accolades, join the #cellxgene-users channel on the CZI Science Slack and say “hi!”.
For any errors, report bugs on Github.
- -
-
- An interactive explorer for single-cell transcriptomics data
-
-
-
- Quick start
-
-
-
-
- Installation
-
-
-
- Gallery
-
-
-
- Cellxgene data portal
-
-
-
- Demo datasets
-
-
-
- Preparing your data
-
-
-
- Launching cellxgene
-
-
-
- Hosting cellxgene
-
-
-
- Annotating data
-
-
-
- Methods
-
-
-
- Troubleshooting
-
-
-
- Roadmap
-
-
-
- Contributing (ideas or code)
-
-
-
- Contact & finding help
-
-
-
- Code
-
We have recently introduced a new feature in cellxgene that enables users to create and edit categorical annotations within the app. We’d love for you to try it out and give us feedback!
- -To get started, run:
- -cellxgene launch mydata.h5ad
-To preserve data provenance, cellxgene does not alter the input h5ad file. Rather, newly-created annotations are saved in a specified CSV file:
annotations-directory/name-########.csv
-annotations-directory is your current working directory (i.e., the directory you were in when you started cellxgene).########; this helps cellxgene identify your file to avoid overwriting your work.Cellxgene allows you to load and edit compatible draft annotations across multiple sessions.
- -Compatible annotations are tabular, with category names as column headers; anndata.obs.index as the index; and categorical values (i.e., fewer unique values per column than specified in --max-category-items, default 1000).
There are two options for updating draft annotations.
- -Cellxgene will automatically find and reload your draft annotations in editable mode.
- -This assumes that:
-1 - The h5ad filename is the same
-2 - You launch cellxgene from the annotations-directory (i.e., the directory that contains your CSV)
-3 - You use the same browser and have not cleared your cookies (we use a small cookie to keep track of which user created the file to avoid accidental overwrites; see FAQ)
This mode is only appropriate for single-user, local cellxgene instances.
- -If you’d like to specify the complete file path for your annotations, you can do so by running:
- -cellxgene launch mydata.h5ad --annotations-file path/to/myfile.csv
-Any changes you make will be reflected in the original CSV. If the file does not exist, it will be created.
-Please note that this file will be overwritten, making this mode inappropriate for hosted / multi-user settings (see below).
Once you’re finished with your annotations, you should finalize and preserve your work by merging your csv into your main h5ad file.
You can do so like this:
- -import pandas as pd
-import scanpy as sc
-
-new_annotations = pd.read_csv('myannotations.csv',
- comment='#',
- dtype='category',
- index_col=0)
-anndata = sc.read('mydata.h5ad')
-anndata.obs = anndata.obs.join(new_annotations)
-As described in the hosted section, we do not officially support hosted or multi-user use of cellxgene. However, we recognize that the app is often adapted for this purpose, and have tried to provide a “safe path” for multi-user setups that avoids overwriting data.
- -Specifying a single file name for multiple contributors will result in data overwriting. To avoid this, you can instead specify an output directory and allow cellxgene to assign filenames.
- -To specify an output directory, run:
- -cellxgene launch mydata.h5ad --annotations-dir path/to/annotations-directory/
-For each user, annotations will be saved as follows:
- -########; this helps cellxgene identify their specific file to avoid overwriting others’ work.annotations-directory/name-########.csvcellxgene autosaves any changes made to your annotations every 3 seconds.
Not to worry! We save the last 10 versions of your annotations in annotations-directory/NAME-backups/
Continuous metadata is important! However, these values (e.g., pseudotime) are the result of statistical analyses that are beyond cellxgene’s visualization- and exploration-focused scope. We do, of course, provide visualization of continuous metadata values computed elsewhere and stored in anndata.obs.
This is most likely because the h5ad file you are working with is not the original file used to generate the annotations! We recommend merging new annotations in on a regular basis for this reason.
- -We place a small cookie (file) in your browser that identifies where your draft annotations are saved. This file never leaves your machine, and is never sent to the cellxgene team or anyone else.
- -Wonderful! This is a relatively new feature; we would love to hear your feedback :)
- -
-
- An interactive explorer for single-cell transcriptomics data
-
-
-
- Quick start
-
-
-
-
- Installation
-
-
-
- Gallery
-
-
-
- Cellxgene data portal
-
-
-
- Demo datasets
-
-
-
- Preparing your data
-
-
-
- Launching cellxgene
-
-
-
- Hosting cellxgene
-
-
-
- Annotating data
-
-
-
- Methods
-
-
-
- Troubleshooting
-
-
-
- Roadmap
-
-
-
- Contributing (ideas or code)
-
-
-
- Contact & finding help
-
-
-
- Code
-
We’d love to hear from you!
- -For questions, suggestions, or accolades, join the #cellxgene-users channel on the CZI Science Slack and say “hi!”.
For any errors, report bugs on Github.
- -The current core team:
- -We would also like to gratefully acknowledge contributions from past core team members:
- -
-
- An interactive explorer for single-cell transcriptomics data
-
-
-
- Quick start
-
-
-
-
- Installation
-
-
-
- Gallery
-
-
-
- Cellxgene data portal
-
-
-
- Demo datasets
-
-
-
- Preparing your data
-
-
-
- Launching cellxgene
-
-
-
- Hosting cellxgene
-
-
-
- Annotating data
-
-
-
- Methods
-
-
-
- Troubleshooting
-
-
-
- Roadmap
-
-
-
- Contributing (ideas or code)
-
-
-
- Contact & finding help
-
-
-
- Code
-
We warmly welcome contributions from the community!
- -To ensure a welcoming experience for our entire community, this project adheres to the Contributor Covenant -code of conduct. -By participating, you are expected to uphold this code. Please report unacceptable behavior -to opensource@chanzuckerberg.com.
- -If you have any questions about any of this stuff, just ask! :)
- -We’d love to hear from you! Please submit any bug reports and feature requests through Github issues.
- -If you are interested in working on cellxgene development, you’ll need to use git to make a copy of the project repository and share your changes.
We have several “rules” (strong suggestions really) for contributions:
- -If your contribution is complex, adds new features, new UI design or otherwise warrants discussion, we highly recommend that you submit a github issue, and engage other contributors in a discussion about the details of your proposed PR. This will save you time in the long run, as many details and decisions can be hashed out ahead-of-time.
-Please submit any direct contributions by forking the repository, creating a feature branch, and submitting a Pull Request.
-First, you’ll need the following installed on your machine
- -Then clone the project
- -git clone https://github.com/chanzuckerberg/cellxgene.git
-This is enough to get you started with editing documentation. If you’d like to contribute code:
- -Build the client web assets from inside the cellxgene folder
make build-for-server-dev
-Install all requirements (we recommend doing this inside a virtual environment)
- -pip install -e .
-You can start the app while developing either by calling cellxgene or by calling python -m server. We recommend using the --debug flag to see more output, which you can include when reporting bugs.
If you have any questions about developing or contributing, come hang out with us by joining the CZI Science Slack and posting in the #cellxgene-dev channel.
This project has made a few key design choices:
- -regl (a webgl library), react, redux, d3, and blueprint to handle rendering large numbers of cells with lots of complex interactivityDepending on your background and interests, you might want to contribute to the frontend, or backend, or both!
- -Please submit any direct contributions via a Pull Request. It’d be great for PRs to include test cases and documentation updates where relevant, though we know the core test suite is itself still a work in progress.
- -The documentation is written in markdown, and lives in the directory cellxgene/docs/posts. You can directly edit or add to these files and submit a Pull Request as described above.
To preview your changes on your local machine, you’ll need to install Jekyll and Ruby using these instructions (you don’t have to know how to program in Ruby, just install it).
- -You can then preview your changes by running cellxgene/docs$ bundle exec jekyll serve and navigating to the url indicated in the terminal.
-
- An interactive explorer for single-cell transcriptomics data
-
-
-
- Quick start
-
-
-
-
- Installation
-
-
-
- Gallery
-
-
-
- Cellxgene data portal
-
-
-
- Demo datasets
-
-
-
- Preparing your data
-
-
-
- Launching cellxgene
-
-
-
- Hosting cellxgene
-
-
-
- Annotating data
-
-
-
- Methods
-
-
-
- Troubleshooting
-
-
-
- Roadmap
-
-
-
- Contributing (ideas or code)
-
-
-
- Contact & finding help
-
-
-
- Code
-
To use these datasets, run:
-cellxgene launch [filename.h5ad] --open
Healthy human PBMCs (10X).
- -cellxgene launch https://cellxgene-example-data.czi.technology/pbmc3k.h5ad
-20 organs and tissues from healthy mice (Smart-Seq2).
-Rich metadata and annotations.
cellxgene launch https://cellxgene-example-data.czi.technology/tabula-muris.h5ad
-22 organs and tissues from healthy mice at ages 3mo, 18mo, 21mo, and 24mo (Smart-Seq2).
-Rich metadata and annotations.
cellxgene launch https://cellxgene-example-data.czi.technology/tabula-muris-senis.h5ad
-
-
- An interactive explorer for single-cell transcriptomics data
-
-
-
- Quick start
-
-
-
-
- Installation
-
-
-
- Gallery
-
-
-
- Demo datasets
-
-
-
- All other datasets
-
-
-
- Preparing your data
-
-
-
- Launching cellxgene
-
-
-
- Hosting cellxgene
-
-
-
- Annotating data
-
-
-
- Methods
-
-
-
- Troubleshooting
-
-
-
- Roadmap
-
-
-
- Contributing (ideas or code)
-
-
-
- Extensions
-
-
-
- Contact & finding help
-
-
-
- Code
-
This project was started with the sole goal of empowering the scientific community to explore and understand their data. -As such, we encourage other scientific tool builders in academia or industry to adopt the patterns, tools, and code from -this project. All code is freely available for reuse under the MIT license.
- -Before extending cellxgene, we encourage you to reach out to us with ideas or questions. It might be possible that an -extension could be directly contributed, which would make it available for a wider audience, or that it’s on our -roadmap and under active development.
- -Please note that cellxgene does not have public APIs. Our development may break extensions. We will document changes to the code base but it is advised that extensions pin the version of cellxgene they develop against.
- -cellxgene Gateway allows you to use with multiple datasets. It -displays an index of available h5ad (anndata) files. When a user clicks on a file name, it launches a Cellxgene Server -instance that loads that particular data file and once it is available proxies requests to that server.
- -cellxgene-VIP enables cellxgene to generate violin, stacked violin, stacked bar, heatmap, volcano, embedding, dot, track, density, 2D density, sankey and dual-gene plot in high-resolution SVG/PNG format. It also performs differential gene expression analysis and provides a Command Line Interface (CLI) for advanced users to perform analysis using python and R.
- -Galaxy is an open source, collaborative, web-based platform for data intensive biomedical research. -Galaxy provides various tools for single-cell data analysis and also infrastructure to the -Galaxy Human Cell Atlas project. cellxgene can be - accessed within Galaxy to view analyzed datasets. See also the relevant publication - -
- -The Single Cell Portal is a data hosting and visualization service. cellxgene can be embedded as an additional view to complement the visualizations provided by the. -Example.
- -FASTGenomics is a collaborative research platform that offers easy-to-use data management and reproducible analytics to drive single-cell research forward. Many of the publicly available datasets in FASTGenomics - as well as your private datasets - can be interactively explored with cellxgene. -See also this example for data from Schulte-Schrepping et al. (Cell, 2020). -Note that it is not necessary to create an account, anonymous login is permitted.
- -
-
- An interactive explorer for single-cell transcriptomics data
-
-
-
- Quick start
-
-
-
-
- Installation
-
-
-
- Gallery
-
-
-
- Cellxgene data portal
-
-
-
- Demo datasets
-
-
-
- Preparing your data
-
-
-
- Launching cellxgene
-
-
-
- Hosting cellxgene
-
-
-
- Annotating data
-
-
-
- Methods
-
-
-
- Troubleshooting
-
-
-
- Roadmap
-
-
-
- Contributing (ideas or code)
-
-
-
- Contact & finding help
-
-
-
- Code
-


Several groups have independently deployed various versions of cellxgene to the web. -Check out the cool data that our users are using cellxgene to explore!
- -Want us to link to your dataset here? Just send us a note!
- -
-
- An interactive explorer for single-cell transcriptomics data
-
-
-
- Quick start
-
-
-
-
- Installation
-
-
-
- Gallery
-
-
-
- Cellxgene data portal
-
-
-
- Demo datasets
-
-
-
- Preparing your data
-
-
-
- Launching cellxgene
-
-
-
- Hosting cellxgene
-
-
-
- Annotating data
-
-
-
- Methods
-
-
-
- Troubleshooting
-
-
-
- Roadmap
-
-
-
- Contributing (ideas or code)
-
-
-
- Contact & finding help
-
-
-
- Code
-
Cellxgene is intended to be used by researchers on their local machines. However, we recognize that sharing and exploring data on the web is important. We’re exploring how we could better support this in the future, and would welcome your input!
- -In the meantime, you can see examples of how other groups have approached this in our gallery. While we don’t officially support web deployment, we’ve offered some guidance below on one way to deploy cellxgene to the web.
- -Please consider the following when deploying cellxgene in any “hosted” environment, especially where access from the broader Internet is possible:
- ---disable-diffexp.cellxgene launch currently uses Flask’s development server, which is not recommended for hosted deployment (see the Flask documentation)If you believe you have found a security-related issue with cellxgene, please report the issue immediately to security@chanzuckerberg.com.
- -The following configuration options require special consideration in any multi-user or hosted environment:
- ---disable-diffexp: the differential expression computation can be resource intensive, in particular for large datasets. If many differential expression calculation requests are made in rapid sequence, it may cause the server CPU or memory resources to be exhausted, and impact the ability of other users to access data. This command line option will disable the differential expression feature, including the removal of the Differential expression button.
--disable-annotations: annotations, which is enabled by default, may not be appropriate for hosted environments. It will write to the local file system, and in extreme cases could be used to abuse (or exceed) file system capacity on the hosting server. We recommend disabling this with this flag.
--annotations-file: this specifies a single file for all end-user annotations, and is incompatible with hosted or multi-user use of cellxgene. Using it will cause loss of user annotation data (ie, the CSV file will be overwritten). If you wish to explore using the annotations feature in a multi-user environment, please refer to the annotations documentation, and in particular the --annotations-dir flag.
There are a number of teams building tools or infrastructure to better utilize cellxgene in a multiple user environment. While we do not endorse any particular solution, you may find the following helpful.
- -If you know of other solutions, drop us a note and we’ll add to this list.
- -The cellxgene team has decided to end our support for our experimental deploy to Heroku button as we move towards providing a supported method of hosted cellxgene.
- -While we no longer directly support Heroku, it is still possible to create a Heroku app via our provided Dockerfile here and Heroku’s documentation.
- -You may have to tweak the Dockerfile like so:
FROM ubuntu:bionic
-
-ENV LC_ALL=C.UTF-8
-ENV LANG=C.UTF-8
-
-RUN apt-get update && \
- apt-get install -y build-essential libxml2-dev python3-dev python3-pip zlib1g-dev python3-requests && \
- pip3 install cellxgene
-
-# ENTRYPOINT ["cellxgene"] # Heroku doesn't work well with ENTRYPOINT
-
-
-and provide a heroku.yml file similar to this:
build:
- docker:
- web: Dockerfile
-run:
- web:
- command:
- - cellxgene launch --host 0.0.0.0 --port $PORT $DATASET # the DATATSET config var must be defined in your dashboard settings.
-Heroku is a quick and easy way to host applications on the cloud.
- -A Heroku deployment of cellxgene means that the app is not running on your local machine. Instead, the app is installed, configured, and run on the Heroku servers (read: cloud).
- -On Heroku’s servers, applications run on a dyno which are Heroku’s implementation and abstraction of containers.
- -Heroku is one of many options available for hosting instances of cellxgene on the web. -Some other options include: Amazon Web Services, Google Cloud Platform, Digital Ocean, and Microsoft Azure.
- -What Heroku enables is a quick, non-technical method of setting up a cellxgene instance. No command line knowledge needed. This also allows machines to access the instance via the internet, so sharing a visualized dataset is as simple as sharing a link.
- -Because cellxgene currently heavily relies on its Python backend for providing the viewer with the necessary data and tooling, it is currently not possible to host cellxgene as a static webpage.
- -This is a good option if you want to quickly deploy an instance of cellxgene to the web. Heroku deployments are free for small datasets up to around 250MBs in size. See below regarding larger datasets.
- -
-
- An interactive explorer for single-cell transcriptomics data
-
-
-
- Quick start
-
-
-
-
- Installation
-
-
-
- Gallery
-
-
-
- Cellxgene data portal
-
-
-
- Demo datasets
-
-
-
- Preparing your data
-
-
-
- Launching cellxgene
-
-
-
- Hosting cellxgene
-
-
-
- Annotating data
-
-
-
- Methods
-
-
-
- Troubleshooting
-
-
-
- Roadmap
-
-
-
- Contributing (ideas or code)
-
-
-
- Contact & finding help
-
-
-
- Code
-
Cellxgene has two parts:
- -cellxgene is the main explorer application, which takes an already-processed h5ad file as input. This is installed by default.cellxgene prepare provides auxiliary functionality for preparing your dataset. This is not installed by default.You’ll need python 3.6+ and an up-to-date version of Google Chrome. -The web UI is tested on OSX and Windows using Chrome, and the python CLI is tested on OSX and Ubuntu (via WSL/Windows). -It should work on other platforms, but if you run into trouble let us know.
- -Python.org has help on installing a recent -version of Python, including the pip package manager. Chrome is available at -Google.com/chrome.
- -To install the cellxgene explorer alone, run:
pip install cellxgene
-To install cellxgene and the optional cellxgene prepare, run:
pip install cellxgene[prepare]
-Note: if the aforementioned optional prepare package installation fails, you can also install these packages directly:
pip install scanpy>=1.3.7 python-igraph louvain>=0.6
-On various Linux platforms, you may also need to install build dependencies first:
- -sudo apt-get install build-essential python-dev
-pip install scanpy>=1.3.7 python-igraph louvain>=0.6
-If you already have cellxgene installed, you can update to the most recent version by running:
pip install cellxgene --upgrade
-To install cellxgene alone, run:
conda create --yes -n cellxgene python=3.7
-conda activate cellxgene
-pip install cellxgene
-To install cellxgene and the optional cellxgene prepare, run:
conda create --yes -n cellxgene python=3.7
-conda activate cellxgene
-pip install cellxgene[prepare]
-To install cellxgene alone, run:
ENV_NAME=cellxgene
-python3.7 -m venv ${ENV_NAME}
-source ${ENV_NAME}/bin/activate
-pip install cellxgene
-To install cellxgene and cellxgene prepare, run:
ENV_NAME=cellxgene
-python3.7 -m venv ${ENV_NAME}
-source ${ENV_NAME}/bin/activate
-pip install cellxgene[prepare]
-Build the image
- -docker build . -t cellxgene
-Run the container and mount data (change data location, --port and --host parameters as needed)
docker run -v "$PWD/example-dataset/:/data/" -p 5005:5005 cellxgene launch --host 0.0.0.0 data/pbmc3k.h5ad
-You will need to use --host 0.0.0.0 to have the container listen to incoming requests from the browser
-
- An interactive explorer for single-cell transcriptomics data
-
-
-
- Quick start
-
-
-
-
- Installation
-
-
-
- Gallery
-
-
-
- Cellxgene data portal
-
-
-
- Demo datasets
-
-
-
- Preparing your data
-
-
-
- Launching cellxgene
-
-
-
- Hosting cellxgene
-
-
-
- Annotating data
-
-
-
- Methods
-
-
-
- Troubleshooting
-
-
-
- Roadmap
-
-
-
- Contributing (ideas or code)
-
-
-
- Contact & finding help
-
-
-
- Code
-
Once you’ve prepared your data for cellxgene, you can launch the app using
- -cellxgene launch mydataset.h5ad --open
-You should see your web browser open with the following
- -
Note: automatic opening of the browser with the --open flag only works on some platforms (eg, OSX). On other platforms you’ll need to directly point to the provided link in your browser.
You can also launch from a URL directly like this:
- -cellxgene launch https://github.com/chanzuckerberg/cellxgene/blob/main/example-dataset/pbmc3k.h5ad
-Support for S3 and GCS is not enabled by default. If you wish to directly access S3 or GFS, install one or both of the following packages:
- - - -For example:
- -pip install s3fs
-cellxgene launch s3://mybucket.s3-us-west-2.amazonaws.com/mydata.h5ad
-launchFor the most up-to-date and comprehensive list of options, run cellxgene launch --help
--open automatically opens the web browser after launching (caveat: only works on some operating systems).
--disable-annotations, --annotations-file & --annotations-dir all have to do with creating new categorical annotations in the application. We have a whole separate page about their usage! :)
--diffexp-lfc-cutoff as explained in the methods, genes are only returned in differential expression if the effect size is above the specified threshold for log fold change. Defaults to 0.01.
--disable-diffexp will disable and hide the Compute Differential Expression feature.
-For large datasets, or datasets loaded with the --backed option, computing differential expression may
-be extremely slow or use excessive resources on the host computer (e.g., memory thrashing).
-Disabling the feature will ensure that this computation is not initiated accidentally.
--backed option instructs cellxgene launch to read the H5AD file in “backed” mode (for more information, see the
-anndata.read_h5ad() documentation).
By default, cellxgene will read the entire H5AD will be into memory at startup, improving application speed and performance.
-Very large datasets may not fit in memory. The “–backed” mode will read the file incrementally, reducing memory
-use, and for large files, improving startup speed. However, this option will also significantly slow
-down access to gene expression histograms, and may render differential expression calculations too slow
-to use (see --disable-diffexp for an option to disable this feature).
--embedding restricts which embeddings will be available in the viewer. By default, all embeddings specified in anndata.obsm['X_name'] will be loaded; if you have many embeddings, you may wish to restrict this list for a speedier launch.
--title adds a title to the viewer. Defaults to file name.
--about adds a link where users can go to find more infomation about the dataset. Requires https.
--obs-names allows you to specify which column in anndata.obs to use as anndata.obs.index.
--var-names allows you to specify which column in anndata.var to use as anndata.var.index.
--max-category-items omits categorical metadata fields that contain more than N distinct values. Defaults to 1000.
-
- An interactive explorer for single-cell transcriptomics data
-
-
-
- Quick start
-
-
-
-
- Installation
-
-
-
- Gallery
-
-
-
- Cellxgene data portal
-
-
-
- Demo datasets
-
-
-
- Preparing your data
-
-
-
- Launching cellxgene
-
-
-
- Hosting cellxgene
-
-
-
- Annotating data
-
-
-
- Methods
-
-
-
- Troubleshooting
-
-
-
- Roadmap
-
-
-
- Contributing (ideas or code)
-
-
-
- Contact & finding help
-
-
-
- Code
-
Gene expression values are pulled from anndata.X. These feed into the histograms, scatterplot, colorscale, and differential expression calculations. We’re working on ways to incorporate anndata.raw and other anndata.layers!
Categorical (e.g., cluster labels) and continuous (e.g., pseudotime) metadata are pulled from anndata.obs. Any column added here will be available for visualization in cellxgene. You can also create new categorical annotations within the application.
cellxgene looks for embeddings (e.g., tSNE, UMAP, PCA, spatial coordinates) in anndata.obsm. These fields must follow the scanpy convention of starting with X_, e.g., anndata.obsm['X_umap']. If an embedding has more than two components, the first two will be used for visualization.
We’re actively working on how to improve differential expression within the app. -N.B.: the current implementation assumes normally distributed values on a linear scale.
- -Currently, we use a Welch’s t-test, which assumes that the two populations are each normally distributed, but may have unequal variance. We use a two-sided t-test against the null hypothesis that the two populations have equal means. P-values are adjusted with the Bonferroni corrrection.
- -To help avoid spurious results, we use the log fold change to filter genes, retaining those where |log2( mean(set1) / mean(set2) )| > 0.01; this threshold can be configured with the --diffexp-lfc-cutoff command. We then sort genes by their associated |t value| and return the top 15 genes.
-
- An interactive explorer for single-cell transcriptomics data
-
-
-
- Quick start
-
-
-
-
- Installation
-
-
-
- Gallery
-
-
-
- Cellxgene data portal
-
-
-
- Demo datasets
-
-
-
- Preparing your data
-
-
-
- Launching cellxgene
-
-
-
- Hosting cellxgene
-
-
-
- Annotating data
-
-
-
- Methods
-
-
-
- Troubleshooting
-
-
-
- Roadmap
-
-
-
- Contributing (ideas or code)
-
-
-
- Contact & finding help
-
-
-
- Code
-
If your data is in h5ad file (from the anndata library) and meets the following requirements, you can go straight to cellxgene launch:
anndata.Xanndata.obsm, specified with the prefix X_ (e.g., by default scanpy stores UMAP coordinates in anndata.obsm['X_umap'])obs DataFrame index. If the index is not unique or does not contain the cell ID, an alternative column can be specified with --obs-namesvar DataFrame index. If the index is not unique or does not contain the gene ID, an alternative column can be specified with --var-namesWe hear you! We’d also love to be able to ingest these files directly. This isn’t currently possible, but in the meantime, you can use sceasy (docs) to convert to h5ad. Seurat also has some handy conversion tools that you can try out.
Yes! You can launch from a URL instead of a filepath. The same data format requirements apply. Please see here for more details.
- -cellxgene will display scanpy-style color
-information
-for category-label pairs. An example of this format is shown below:
>>> category = "louvain"
->>> # colors stored in adata.uns must be matplotlib-compatible color information
->>> adata.uns[f"{category}_colors"]
-array(['#1f77b4', '#ff7f0e', '#2ca02c', '#d62728', '#9467bd', '#8c564b', '#e377c2', '#bcbd22'], dtype='<U7')
->>> # there must be a matching category in adata.obs
->>> category in adata.obs
-True
-To test that you’ve done this properly, check that for your given category the number of colors match the number of category values and that the second command below results in a mapping from categories to colors.
>>> len(adata.obs[category].cat.categories) == len(adata.uns[f"{category}_colors"])
-True
->>> dict(zip(adata.obs[category].cat.categories, adata.uns[f"{category}_colors"]))
-{'CD4 T cells': '#1f77b4', 'CD14+ Monocytes': '#ff7f0e', 'B cells': '#2ca02c', 'CD8 T cells': '#d62728', 'NK cells': '#9467bd', 'FCGR3A+ Monocytes': '#8c564b', 'Dendritic cells': '#e377c2', 'Megakaryocytes': '#bcbd22'}
-You can disable this feature using the --disable-custom-colors flag for cellxgene launch. cellxgene will then chose colors from its standard color palettes.
cellxgene prepareIf your data is in a different format, and/or you still need to perform dimensionality reduction and/or clustering, cellxgene can do that for you with the prepare command.
cellxgene prepare?cellxgene prepare offers an easy command line interface (CLI) to preliminarily wrangle your data into the required format for previewing it with cellxgene. It runs scanpy under the hood and can read in any format that is currently supported by scanpy (including mtx, loom, and more listed in the scanpy documentation).
prepare uses scanpy to:
You can control which steps to run and their methods (when applicable), via the CLI. The CLI also includes options for computing QC metrics, enforcing matrix sparcity, specifying index names, and plotting output.
- -prepare not?cellxgene prepare is not meant as a way to formally process or analyze your data. It’s simply a utility for quickly wrangling your data into cellxgene-compatible format and computing a “vanilla” embedding so you can try out cellxgene and get a general sense of a dataset.
cellxgene prepareTo add cellxgene prepare to your cellxgene installation, run
-pip install cellxgene[prepare]
Then run prepare on your data with:
cellxgene prepare dataset.h5ad --output=dataset-processed.h5ad
-This will load the input data, perform PCA and nearest neighbor calculations, compute UMAP and tSNE embeddings and louvain cluster assignments, and save the results in a new file called dataset-processed.h5ad that can be loaded using cellxgene launch.
As a quick example, let’s construct a command to use prepare to take a raw expression matrix and generate a processed h5ad ready to visualize with cellxgene.
We’ll start off using the raw data from the pbmc3k dataset. This dataset is described here, and is available as part of the scanpy package. For this example, we’ll assume this raw data is stored in a file called pbmc3k-raw.h5ad.
Our prepare command looks like this:
cellxgene prepare pbmc3k-raw.h5ad \
- --run-qc \ # (A)
- --recipe seurat \ # (B)
- --layout tsne --layout umap \ # (C)
- --output pbmc3k-prepared.h5ad # (D)
-Let’s look at what prepare is doing to our data, and how each step relates to the command above. You can see a walkthrough of what’s going on under the hood for this example in this notebook.
(A) - Compute quality control metrics and store this in our AnnData object for later inspection
-(B) - Normalize the expression matrix using a basic preprocessing recipe
-(auto) - Do some preprocessing to run PCA and compute the neighbor graph
-(auto) - Infer clusters with the Louvain algorithm and store these labels to visualize later
-(C) - Compute and store UMAP and tSNE embeddings
-(D) - Write results to file
prepareFor the most up-to-date and comprehensive list of options, run cellxgene prepare --help
--embedding controls which dimensionality reduction algorithm is applies to your data.
-Options are umap and/or tsne. Defaults to both.
--recipe controls which normalization steps to apply to your data, based on one of the preprocessing recipes included with scanpy.
-These recipes include steps like cell filtering and gene selection; see the scanpy documentation for more details.
-Options are none, seurat, or zheng17. Defaults to none.
--sparse is a flag determines whether to enforce a sparse matrix. For large datasets, prepare can take a long time to run (a few minutes for datasets with 10-100k cells, up to an hour or more for datasets with >100k cells). If you want prepare to run faster we recommend using the sparse option.
-If this flag is not included, default is False
--skip-qc by default, cellxgene prepare will compute quality control metrics (saved to anndata.obs and anndata.var) as described in the scanpy documentation. Pass this flag if you would like to skip this step.
--make-obs-names-unique / --make-var-names-unique determine whether to rename obs (cell) / var (gene) names, respectively, to be unique.
-Default is True.
--set-obs-names controls which field in anndata.obs (cell metadata) is used as the index for cells (e.g., a cell ID column).
-Default is anndata.obs.names
--set-var-names controls which field in anndata.var (gene metadata) is used as the index for genes.
-Default is anndata.var.names
--output and --overwrite control where the processed data is saved.
-
- An interactive explorer for single-cell transcriptomics data
-
-
-
- Quick start
-
-
-
-
- Installation
-
-
-
- Gallery
-
-
-
- Cellxgene data portal
-
-
-
- Demo datasets
-
-
-
- Preparing your data
-
-
-
- Launching cellxgene
-
-
-
- Hosting cellxgene
-
-
-
- Annotating data
-
-
-
- Methods
-
-
-
- Troubleshooting
-
-
-
- Roadmap
-
-
-
- Contributing (ideas or code)
-
-
-
- Contact & finding help
-
-
-
- Code
-
cellxgene makes it easier for biologists to collaboratively explore and understand their single-cell RNA-seq data. -In the near term, we are focused on continuing to enable fast, interactive exploration of single-cell data, supporting collaborative workflows in single-cell analysis, and improving user support. -If you have questions or feedback about this roadmap, please submit an issue on GitHub. -Please note: this roadmap is subject to change.
- -Last updated: June 25, 2019
- -Biologists need to understand how variables (stored in metadata) are associated with one another and how they relate to changes in gene expression. -Building upon visualization features that reveal categorical metadata relationships (cluster occupancy) and gene expression relationships (scatterplot), we plan to add exploratory visualization components that enable investigation of relationships between metadata and gene expression. -See issue #616 for more details.
- -While exploring a transcriptomics dataset, scientists need to understand the biological context of genes. -This context may be provided by user-defined gene metadata or publicly available gene databases. -We plan to support augmenting gene names with additional information that is useful to biologists. -See issue #96 for more detail.
- -cellxgene offers exploratory visualizations that are critical for manual annotation workflows, especially in collaborative environments. -We plan to support manually annotating cells with labels (i.e., cell type or QC flags), and their easy export for downstream analysis. -See issue #524 for more details.
- -Many biologists prefer not to interact with the command line and need an OS-native experience when using cellxgene. -We plan to implement a point-and-click installation and launch experience so that users can easily load data into cellxgene. -See issue #687 for details.
- -For computational biologists, saving h5ad files then loading them into cellxgene is a point of friction. -We plan to support importing cellxgene as a Python package so that users can launch cellxgene directly from an interactive environment (such as Jupyter, IPython, or Spyder), and pass data to and from the cellxgene UI.
- -cellxgene has some specific expectations about how data is stored. -We want to ensure that new users can get started easily and learn how to use cellxgene with their own data. -We plan to improve documentation on getting started, installation, data, and contributing. -See issue #533 for more details.
- -
-
- An interactive explorer for single-cell transcriptomics data
-
-
-
- Quick start
-
-
-
-
- Installation
-
-
-
- Gallery
-
-
-
- Cellxgene data portal
-
-
-
- Demo datasets
-
-
-
- Preparing your data
-
-
-
- Launching cellxgene
-
-
-
- Hosting cellxgene
-
-
-
- Annotating data
-
-
-
- Methods
-
-
-
- Troubleshooting
-
-
-
- Roadmap
-
-
-
- Contributing (ideas or code)
-
-
-
- Contact & finding help
-
-
-
- Code
-
pip install cellxgene and got a weird error I don’t understandThis may happen, especially as we work out bugs in our installation process! Please create a new Github issue, explain what you did, and include all the error messages you saw. It’d also be super helpful if you call pip freeze and include the full output alongside your issue.
If your dataset requires gigabytes of disk space, you may need to select an appropriate storage format in order to effectively utilize cellxgene. Tips and tricks:
cellxgene is optimized for columnar data access. For large datasets, format the expression matrix (.X) as either a SciPy CSC sparse matrix or a dense Numpy array (whichever creates a smaller h5ad file). If you are using cellxgene prepare, include the --sparse flag to ensure .X is formatted as a CSC sparse matrix (by default, .X will be a dense matrix).cellxgene loads the dataset into memory, and start time is directly proportional to h5ad file size and the speed of your file system. Expect that large (e.g., million cell) datasets will take minutes to load, even on relatively fast computers with a high performance local hard drive. Once loaded, exploring metadata should still be quick. If this start time is a problem, try the --backed flag, which will attempt to lazily load data as needed (caveat: subsequent data access may be slower).--disable-diffexp flag. For datasets that are extremely large, you may also find the --backed flag improves your ability to explore them.This is likely because you do not have node and npm installed, we recommend using nvm if you’re new to using these tools.
- -
-
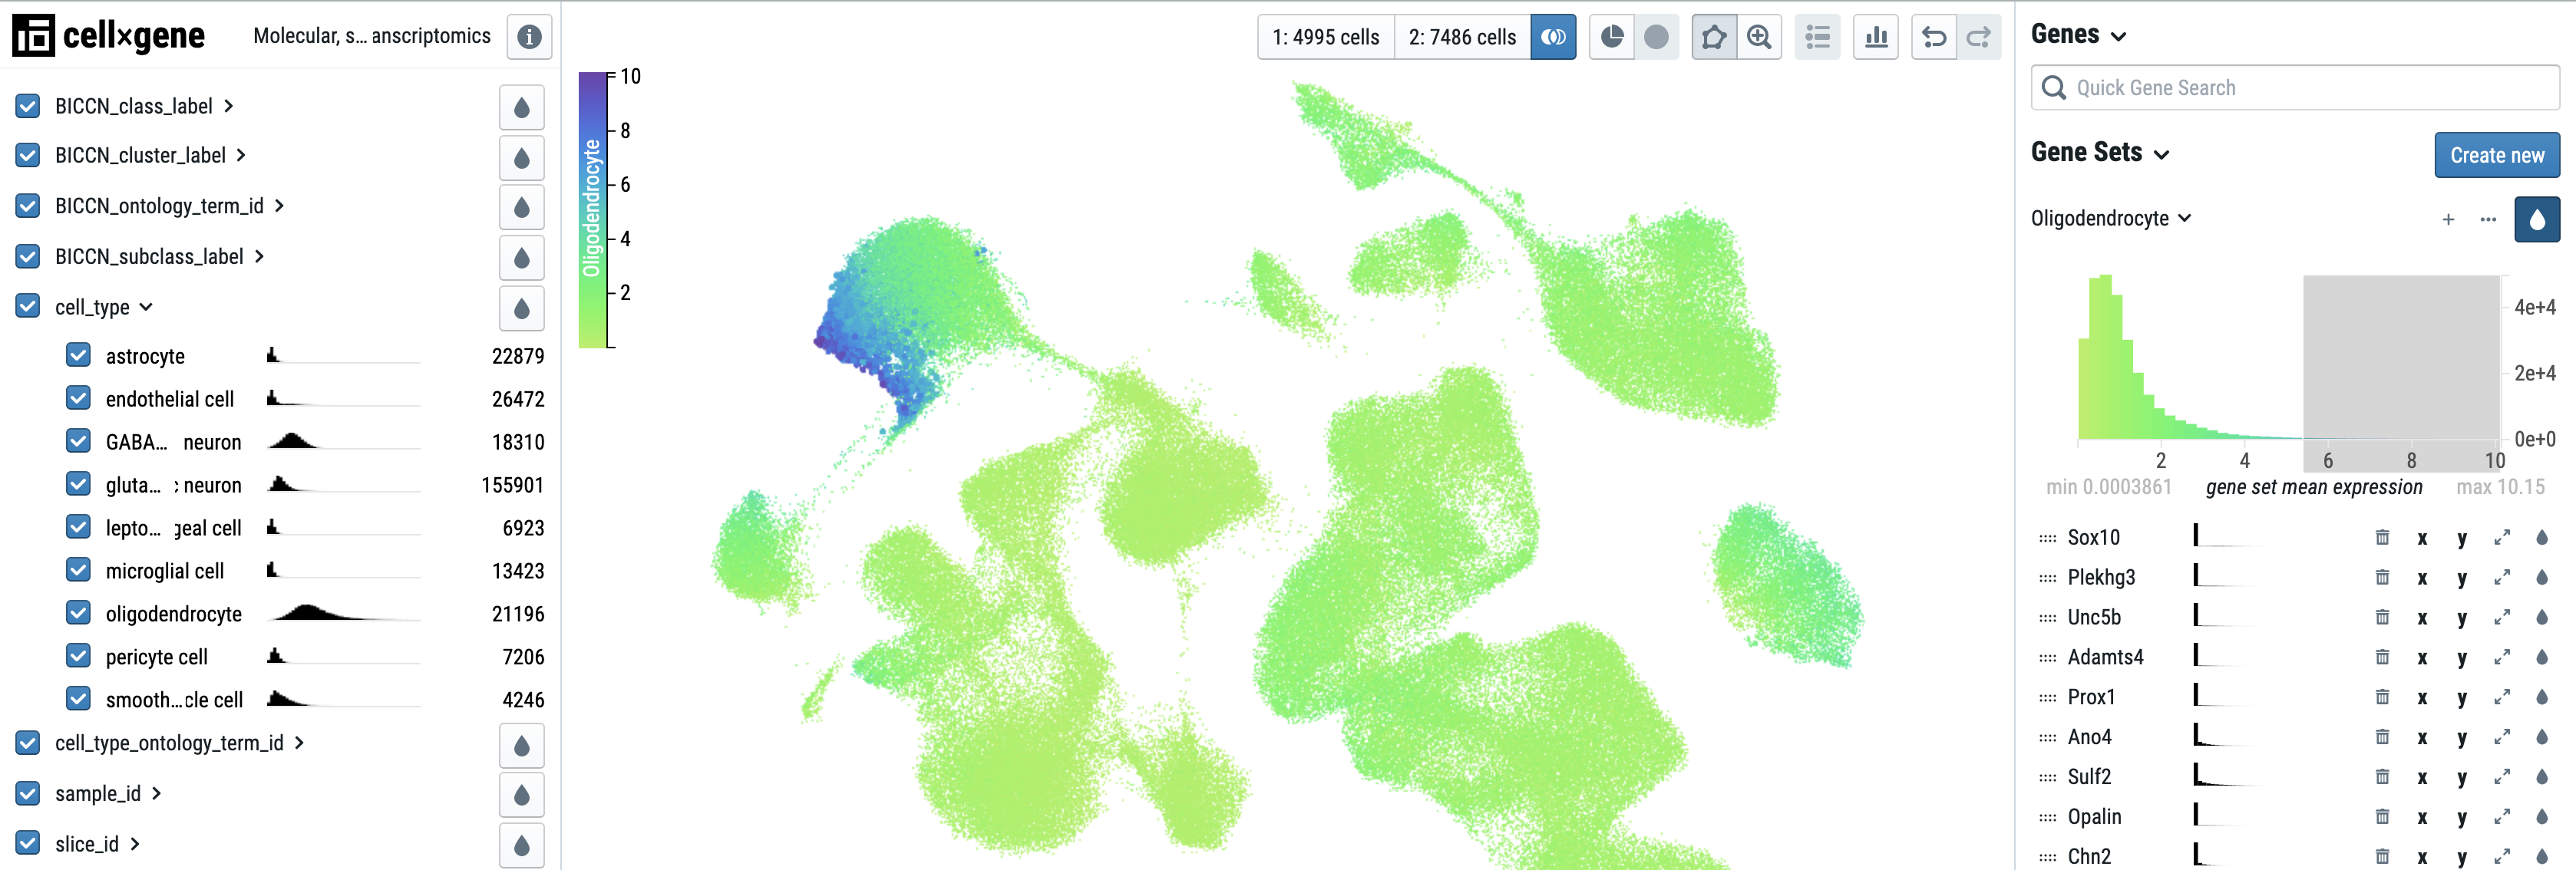
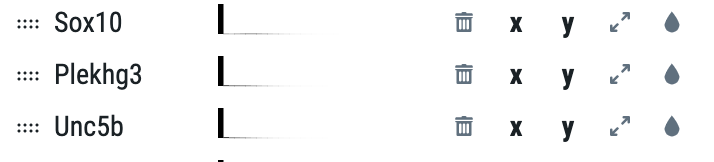
-For each individual gene within a gene set, use the icons to the right of the gene name to plot on the x or y axis of the scatterplot, expand the histogram, or color by that gene.
-
-
-
----
-
-### Creating a gene set
-
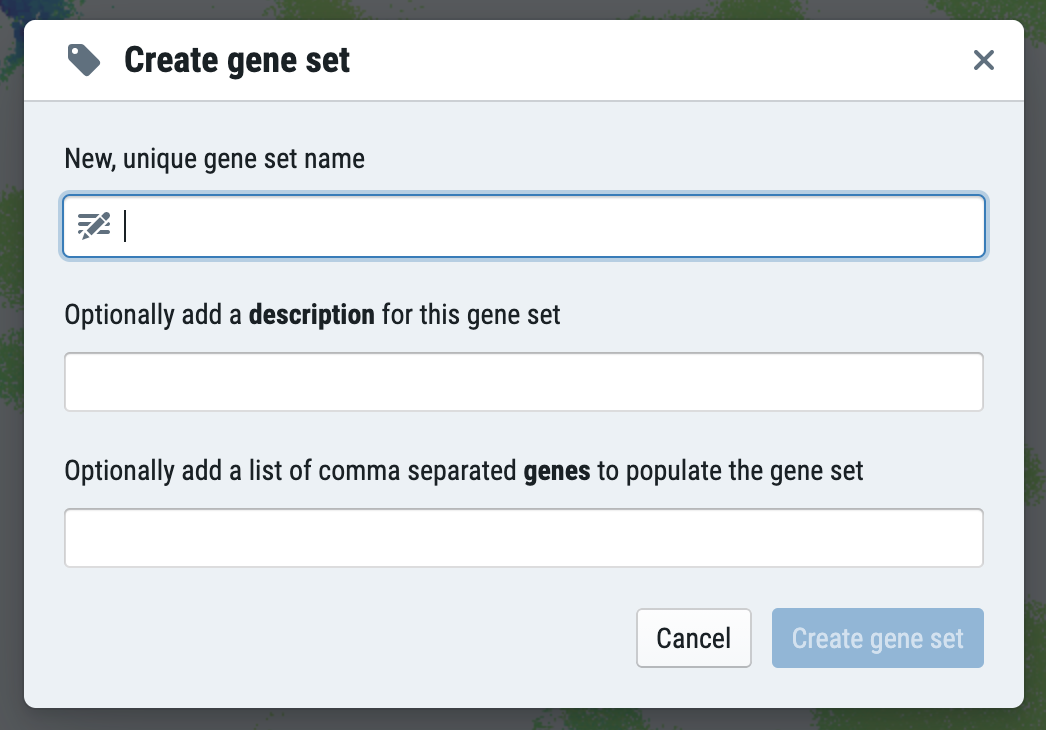
-To create a gene set, click "Create new." You can name your gene set, add an optional description, and add a comma separated list of genes.
-
-
-
----
-
-### Editing a gene set
-
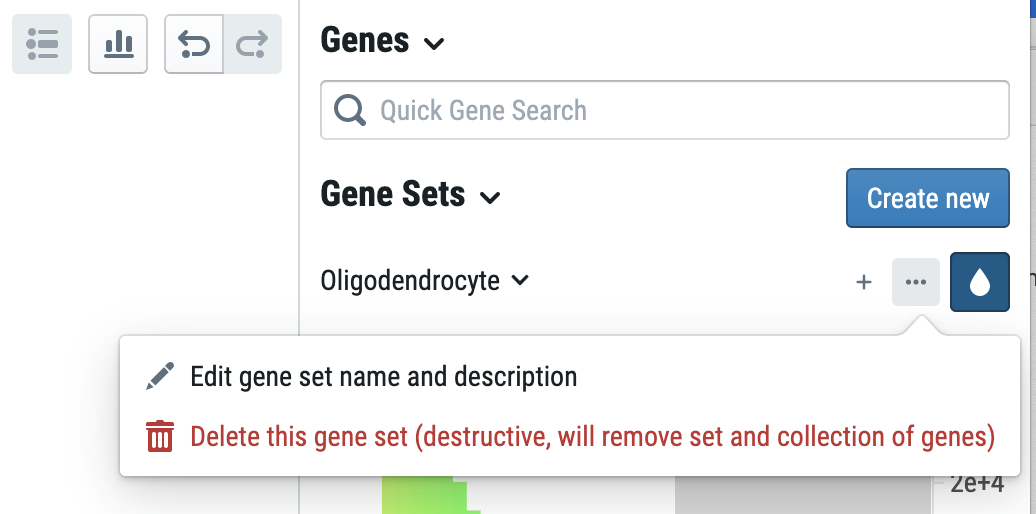
-Users may delete a gene set or edit the name and description of a gene set.
-
-
-
-Users may also add additional genes to the gene set by clicking the plus button next to the name of the gene set.
-
-All changes will be saved in the file designated with the command --gene-sets-file. If no file is specified, a CSV file will be created in the user's default directory.
diff --git a/docs/gene_sets_example.csv b/docs/gene_sets_example.csv
deleted file mode 100644
index dd9d6e6e..00000000
--- a/docs/gene_sets_example.csv
+++ /dev/null
@@ -1,6 +0,0 @@
-gene_set_name,gene_set_description,gene_symbol,gene_description,provenance1,provenance1_description,provenance2,provenance2_description,
-club.cell,Genes that when expressed together uniquely define club cells,CCKAR,This gene encodes a G protein,Pubmed ID XYZ123,Primary Pubmed ID,Pubmed ID 576869,Secondary Pubmed ID,
-club.cell,Genes that when expressed together uniquely define club cells,SCGB3A2,protein coding gene associated with asthma,Pubmed ID ABC456,Primary Pubmed ID,Pubmed ID 2928374,Secondary Pubmed ID,
-club.cell,Genes that when expressed together uniquely define club cells,CYP2F2,protein coding gene associated with metabolic processes,Pubmed ID DCF678,Primary Pubmed ID,Pubmed ID XYZ123,Secondary Pubmed ID,
-macrophage,Genes that when expressed together uniquely define macrophages,CD68,Critical to macrophages,,,,,
-macrophage,Genes that when expressed together uniquely define macrophages,CD163,Also critical to macrophages,,,,,
diff --git a/docs/index.html b/docs/index.html
new file mode 100644
index 00000000..a1a5c49f
--- /dev/null
+++ b/docs/index.html
@@ -0,0 +1,6 @@
+
+
+
+
+
+
diff --git a/docs/index.md b/docs/index.md
deleted file mode 100644
index b147a754..00000000
--- a/docs/index.md
+++ /dev/null
@@ -1,33 +0,0 @@
----
-title: Index
-subtitle: Index
-layout: default
----
-# Quick start
-
-Whether you need to visualize one thousand cells or one million, cellxgene helps you gain insight into your single-cell data.
-
-To install cellxgene you need Python 3.6+. We recommend [installing cellxgene into a conda or virtual environment.](posts/install)
-
-Install the package.
-``` bash
-pip install cellxgene
-```
-
-Launch cellxgene with an example [anndata](https://anndata.readthedocs.io/en/latest/) file
-
-``` bash
-cellxgene launch https://cellxgene-example-data.czi.technology/pbmc3k.h5ad
-```
-
-To explore more datasets already formatted for cellxgene, check out the [Demo data](posts/demo-data) or
-see [Preparing your data](posts/prepare) to learn more about formatting your own
-data for cellxgene.
-
-# Getting help
-
-We'd love to hear from you!
-
-For questions, suggestions, or accolades, [join the `#cellxgene-users` channel on the CZI Science Slack](https://join-cellxgene-users.herokuapp.com/) and say "hi!".
-
-For any errors, [report bugs on Github](https://github.com/chanzuckerberg/cellxgene/issues).
diff --git a/docs/posts/annotations.md b/docs/posts/annotations.md
deleted file mode 100644
index 8b7892d5..00000000
--- a/docs/posts/annotations.md
+++ /dev/null
@@ -1,121 +0,0 @@
----
-layout: default
-title: annotations
-description: Creating annotations
----
-
-# Creating annotations in cellxgene
-
-We have recently introduced a new feature in cellxgene that enables users to create and edit categorical annotations within the app. We'd love for you to try it out and [give us feedback](contact)!
-
-# Data lifecycle for annotations
-
-## 1. Creating annotations (quickstart)
-
-To get started, run:
-
-```
-cellxgene launch mydata.h5ad
-```
-
-To preserve data provenance, **`cellxgene` does not alter the input h5ad file**. Rather, newly-created annotations are saved in a specified CSV file:
-
-```
-annotations-directory/name-########.csv
-```
-
-- The default `annotations-directory` is your current working directory (i.e., the directory you were in when you started cellxgene).
-- You will be prompted to enter a name for your annotations the first time you create a new category.
-- We also assign a unique identifier in the form of an 8-character suffix, `########`; this helps cellxgene identify your file to avoid overwriting your work.
-
-## 2. Loading, editing and updating existing draft annotations
-
-Cellxgene allows you to load and edit compatible draft annotations across multiple sessions.
-
-Compatible annotations are tabular, with category names as column headers; `anndata.obs.index` as the index; and categorical values (i.e., fewer unique values per column than specified in `--max-category-items`, default 1000).
-
-There are two options for updating draft annotations.
-
-### Autodetect annotations CSV
-
-Cellxgene will automatically find and reload your draft annotations in editable mode.
-
-This assumes that:
-1 - The h5ad filename is the same
-2 - You launch cellxgene from the `annotations-directory` (i.e., the directory that contains your CSV)
-3 - You use the same browser and have not cleared your cookies (we use a small cookie to keep track of which user created the file to avoid accidental overwrites; see FAQ)
-
-### Specify an annotations CSV
-
-**This mode is only appropriate for single-user, local cellxgene instances.**
-
-If you'd like to specify the complete file path for your annotations, you can do so by running:
-
-```
-cellxgene launch mydata.h5ad --annotations-file path/to/myfile.csv
-```
-
-Any changes you make will be reflected in the original CSV. If the file does not exist, it will be created.
-**Please note that this file will be overwritten, making this mode inappropriate for hosted / multi-user settings (see below).**
-
-### 3. Merging draft annotations with the main h5ad file
-
-Once you're finished with your annotations, you should finalize and preserve your work by merging your `csv` into your main `h5ad` file.
-
-You can do so like this:
-
-```
-import pandas as pd
-import scanpy as sc
-
-new_annotations = pd.read_csv('myannotations.csv',
- comment='#',
- dtype='category',
- index_col=0)
-anndata = sc.read('mydata.h5ad')
-anndata.obs = anndata.obs.join(new_annotations)
-```
-
-# Annotations by multiple users
-
-As described in the [hosted](hosted) section, we do not officially support hosted or multi-user use of cellxgene. However, we recognize that the app is often adapted for this purpose, and have tried to provide a "safe path" for multi-user setups that avoids overwriting data.
-
-Specifying a single file name for multiple contributors will result in data overwriting. To avoid this, you can instead specify an output directory and allow cellxgene to assign filenames.
-
-To specify an output directory, run:
-
-```
-cellxgene launch mydata.h5ad --annotations-dir path/to/annotations-directory/
-```
-
-For each user, annotations will be saved as follows:
-
-- Each user will be prompted to enter a name for their annotations the first time they create a new category.
-- We also assign a unique identifier in the form of an 8-character suffix, `########`; this helps cellxgene identify their specific file to avoid overwriting others' work.
-- Any annotations created in the application will be autosaved in `annotations-directory/name-########.csv`
-
-## FAQ
-
-### How do I know my annotations are saved?
-
-`cellxgene` autosaves any changes made to your annotations every 3 seconds.
-
-### I think I deleted my annotations! Oh noes!
-
-Not to worry! We save the last 10 versions of your annotations in `annotations-directory/NAME-backups/`
-
-### What about creating continuous annotations?
-
-Continuous metadata is important! However, these values (e.g., pseudotime) are the result of statistical analyses that are beyond cellxgene's visualization- and exploration-focused scope. We do, of course, provide visualization of continuous metadata values computed elsewhere and stored in `anndata.obs`.
-
-### I keep getting weird index errors when trying to join my annotations to my anndata?
-
-This is most likely because the h5ad file you are working with is not the original file used to generate the annotations! We recommend merging new annotations in on a regular basis for this reason.
-
-### How do you remember my unique ID to match my cellxgene session with my annotations file?
-
-We place a small cookie (file) in your browser that identifies where your draft annotations are saved. This file never leaves your machine, and is never sent to the cellxgene team or anyone else.
-
-### I have feedback and ideas for you!
-
-Wonderful! This is a relatively new feature; we would _love_ to [hear your feedback](contact) :)
diff --git a/docs/posts/contact.md b/docs/posts/contact.md
deleted file mode 100644
index 37389381..00000000
--- a/docs/posts/contact.md
+++ /dev/null
@@ -1,26 +0,0 @@
----
-layout: default
-title: Contact
-description: Contact
----
-# Get in touch
-
-We'd love to hear from you!
-
-For questions, suggestions, or accolades, [join the `#cellxgene-users` channel on the CZI Science Slack](https://join-cellxgene-users.herokuapp.com/) and say "hi!".
-
-For any errors, [report bugs on Github](https://github.com/chanzuckerberg/cellxgene/issues).
-
-# Team
-
-The current core team:
-
-- Colin Megill, frontend & product design
-- Bruce Martin, software engineer
-- Sidney Bell, computational biologist
-- Lia Prins, designer
-- Severiano Badajoz, software engineer
-
-We would also like to gratefully acknowledge contributions from past core team members:
-
-- Charlotte Weaver, software engineer
diff --git a/docs/posts/contribute.md b/docs/posts/contribute.md
deleted file mode 100644
index e9de7617..00000000
--- a/docs/posts/contribute.md
+++ /dev/null
@@ -1,75 +0,0 @@
-# Code of conduct
-
-We warmly welcome contributions from the community!
-
-To ensure a welcoming experience for our entire community, this project adheres to the Contributor Covenant
-[code of conduct](https://github.com/chanzuckerberg/.github/tree/master/CODE_OF_CONDUCT.md).
-By participating, you are expected to uphold this code. Please report unacceptable behavior
-to opensource@chanzuckerberg.com.
-
-If you have any questions about any of this stuff, just ask! :)
-
-# Contributing ideas and issues
-
-We'd love to hear from you! Please submit any bug reports and feature requests through [Github issues](https://github.com/chanzuckerberg/cellxgene/issues).
-
-# Direct contributions
-
-## Getting started
-
-If you are interested in working on `cellxgene` development, you'll need to use git to make a copy of the [project repository](https://help.github.com/en/github/collaborating-with-issues-and-pull-requests/working-with-forks) and share your changes.
-
-We have several "rules" (strong suggestions really) for contributions:
-
-1. If your contribution is complex, adds new features, new UI design or otherwise warrants discussion, we highly recommend that you submit a github issue, and engage other contributors in a discussion about the details of your proposed PR. This will save you time in the long run, as many details and decisions can be hashed out ahead-of-time.
-
-2. Please submit any direct contributions by [forking the repository](https://help.github.com/en/github/collaborating-with-issues-and-pull-requests/working-with-forks), creating a feature branch, and [submitting a Pull Request](https://help.github.com/en/github/collaborating-with-issues-and-pull-requests/creating-a-pull-request).
-
-First, you'll need the following installed on your machine
-
-- python 3.6+
-- node and npm (we recommend using [nvm](https://github.com/creationix/nvm) if this is your first time with node)
-
-Then clone the project
-
-```
-git clone https://github.com/chanzuckerberg/cellxgene.git
-```
-
-This is enough to get you started with editing documentation. If you'd like to contribute code:
-
-Build the client web assets from inside the `cellxgene` folder
-
-```
-make build-for-server-dev
-```
-
-Install all requirements (we recommend doing this inside a [virtual environment](https://docs.python.org/3/tutorial/venv.html))
-
-```
-pip install -e .
-```
-
-You can start the app while developing either by calling `cellxgene` or by calling `python -m server`. We recommend using the `--debug` flag to see more output, which you can include when reporting bugs.
-
-If you have any questions about developing or contributing, come hang out with us by joining the [CZI Science Slack](https://join-cellxgene-users.herokuapp.com/) and posting in the `#cellxgene-dev` channel.
-
-## Contributing code
-
-This project has made a few key design choices:
-
-- The front-end is built with [`regl`](https://github.com/regl-project/regl) (a webgl library), [`react`](https://reactjs.org/), [`redux`](https://redux.js.org/), [`d3`](https://github.com/d3/d3), and [`blueprint`](https://blueprintjs.com/docs/#core) to handle rendering large numbers of cells with lots of complex interactivity
-- The app is designed with a client-server model that can support a range of existing analysis packages for Python-based backend computational tasks (currently built for [scanpy](https://github.com/theislab/scanpy))
-- The client uses fast cross-filtering to handle selections and comparisons across subsets of data
-
-Depending on your background and interests, you might want to contribute to the frontend, or backend, or both!
-
-Please submit any direct contributions via a Pull Request. It'd be great for PRs to include test cases and documentation updates where relevant, though we know the core test suite is itself still a work in progress.
-
-## Contributing documentation
-
-The documentation is written in [markdown](https://github.com/adam-p/markdown-here/wiki/Markdown-Cheatsheet), and lives in the directory `cellxgene/docs/posts`. You can directly edit or add to these files and submit a Pull Request as described above.
-
-To preview your changes on your local machine, you'll need to install Jekyll and Ruby using [these instructions](https://jekyllrb.com/docs/installation/) (you don't have to know how to program in Ruby, just install it).
-
-You can then preview your changes by running `cellxgene/docs$ bundle exec jekyll serve` and navigating to the url indicated in the terminal.
diff --git a/docs/posts/demo-data.md b/docs/posts/demo-data.md
deleted file mode 100644
index 8a000486..00000000
--- a/docs/posts/demo-data.md
+++ /dev/null
@@ -1,50 +0,0 @@
----
-layout: default
-title: demo-data
-description: Demo datasets
----
-
-# Example datasets
-**To use these datasets, run:**
-`cellxgene launch [filename.h5ad] --open`
-
-### Peripheral blood mononuclear cells
-Healthy human PBMCs (10X).
-
-- Source: [10X genomics](https://support.10xgenomics.com/single-cell-gene-expression/datasets/1.1.0/pbmc3k)
-- Cells: 2,638
-- File size: 19MB
-- [Raw data](http://cf.10xgenomics.com/samples/cell-exp/1.1.0/pbmc3k/pbmc3k_filtered_gene_bc_matrices.tar.gz)
-- [Processing](https://github.com/chanzuckerberg/cellxgene-vignettes/blob/master/dataset-processing/pbmc3k-processing.ipynb)
-- Launch:
-```
-cellxgene launch https://cellxgene-example-data.czi.technology/pbmc3k.h5ad
-```
-
-### Tabula muris
-20 organs and tissues from healthy mice (Smart-Seq2).
-Rich metadata and annotations.
-
-- Source: [bioRxiv, CZBiohub](https://www.biorxiv.org/content/10.1101/237446v2)
-- Cells: 45,423
-- File size: 174MB
-- [Raw data](https://figshare.com/projects/Tabula_Muris_Transcriptomic_characterization_of_20_organs_and_tissues_from_Mus_musculus_at_single_cell_resolution/27733)
-- [Processing](https://github.com/chanzuckerberg/cellxgene-vignettes/blob/master/dataset-processing/tabula-muris-processing.ipynb)
-- Launch:
-```
-cellxgene launch https://cellxgene-example-data.czi.technology/tabula-muris.h5ad
-```
-
-### Tabula muris senis
-22 organs and tissues from healthy mice at ages 3mo, 18mo, 21mo, and 24mo (Smart-Seq2).
-Rich metadata and annotations.
-
-- Source: [bioRxiv, CZBiohub](https://www.biorxiv.org/content/10.1101/661728v1)
-- Cells: 81,478
-- File size: 3.9GB
-- Raw data [geo link coming soon!]
-- [Processing](https://www.biorxiv.org/content/10.1101/661728v1)
-- Launch:
-```
-cellxgene launch https://cellxgene-example-data.czi.technology/tabula-muris-senis.h5ad
-```
diff --git a/docs/posts/extensions.md b/docs/posts/extensions.md
deleted file mode 100644
index 5b25c958..00000000
--- a/docs/posts/extensions.md
+++ /dev/null
@@ -1,39 +0,0 @@
-# Extensions
-
-This project was started with the sole goal of empowering the scientific community to explore and understand their data.
-As such, we encourage other scientific tool builders in academia or industry to adopt the patterns, tools, and code from
-this project. All code is freely available for reuse under the [MIT license](https://opensource.org/licenses/MIT).
-
-Before extending cellxgene, we encourage you to reach out to us with ideas or questions. It might be possible that an
-extension could be directly contributed, which would make it available for a wider audience, or that it's on our
-[roadmap](./roadmap.md) and under active development.
-
-Please note that cellxgene does not have public APIs. Our development may break extensions. We will document changes to the code base but it is advised that extensions pin the version of cellxgene they develop against.
-
-## Example Reuse & extensions
-
-#### cellxgene Gateway
-
-[cellxgene Gateway](https://github.com/Novartis/cellxgene-gateway) allows you to use with multiple datasets. It
-displays an index of available h5ad (anndata) files. When a user clicks on a file name, it launches a Cellxgene Server
-instance that loads that particular data file and once it is available proxies requests to that server.
-
-#### cellxgene-VIP (Visualization in Plugin)
-
-[cellxgene-VIP](https://github.com/interactivereport/cellxgene_VIP) enables cellxgene to generate violin, stacked violin, stacked bar, heatmap, volcano, embedding, dot, track, density, 2D density, sankey and dual-gene plot in high-resolution SVG/PNG format. It also performs differential gene expression analysis and provides a Command Line Interface (CLI) for advanced users to perform analysis using python and R.
-
-#### Galaxy
-
-[Galaxy](https://singlecell.usegalaxy.eu/) is an open source, web-based platform for data intensive biomedical research. cellxgene can be accessed within Galaxy to view analyzed datasets.
-See also the relevant [publication](https://www.biorxiv.org/content/10.1101/2020.06.06.137570v1.full.pdf)
-
-#### Single Cell Portal
-
-The [Single Cell Portal](https://singlecell.broadinstitute.org/single_cell) is a data hosting and visualization service. cellxgene can be embedded as an additional view to complement the visualizations provided by the.
-[Example](https://singlecell.broadinstitute.org/single_cell/study/SCP807/atlas-of-healthy-and-shiv-infected-non-human-primate-lung-and-ileum-ace2-cells).
-
-#### FASTGenomics
-
-[FASTGenomics](https://beta.fastgenomics.org/) is a collaborative research platform that offers easy-to-use data management and reproducible analytics to drive single-cell research forward. Many of the publicly available datasets in FASTGenomics - as well as your private datasets - can be interactively explored with cellxgene.
-See also this [example](https://beta.fastgenomics.org/datasets/detail-dataset-952687f71ef34322a850553c4a24e82e#Cellxgene) for data from [Schulte-Schrepping et al. (Cell, 2020)](https://beta.fastgenomics.org/p/schulte-schrepping_covid19).
-Note that it is not necessary to create an account, anonymous login is permitted.
diff --git a/docs/posts/gallery.md b/docs/posts/gallery.md
deleted file mode 100644
index 01f45301..00000000
--- a/docs/posts/gallery.md
+++ /dev/null
@@ -1,44 +0,0 @@
----
-title: Gallery
-subtitle: Features & examples
-layout: default
----
-
-# Features
-
-### Cross-filter cells and color by metadata
-
-
-
-### Compare groups of cells with differential expression
-
-
-
-### See how metadata and gene expression break down across categories
-
-
-
-### Find cells where a gene is expressed
-
-
-
-### Compare expression of multiple genes
-
-
-
-# Interactive demos
-
-Several groups have independently [deployed](hosted) various versions of cellxgene to the web.
-Check out the cool data that our users are using cellxgene to explore!
-
-### [Kidney cell atlas](https://www.kidneycellatlas.org/)
-
-### [Tabula muris senis](https://tabula-muris-senis.ds.czbiohub.org/)
-
-### [Hemocytes](https://hemocytes.cellgeni.sanger.ac.uk/)
-
-### [Melanoma](https://melanoma.cellgeni.sanger.ac.uk/)
-
-### [CZI's own cellxgene site](https://cellxgene.cziscience.com/)
-
-_Want us to link to your dataset here? [Just send us a note!](contact)_
diff --git a/docs/posts/hosted.md b/docs/posts/hosted.md
deleted file mode 100644
index 073ede26..00000000
--- a/docs/posts/hosted.md
+++ /dev/null
@@ -1,103 +0,0 @@
-# Hosting cellxgene on the web
-
-Cellxgene is intended to be used by researchers on their local machines. However, we recognize that sharing and exploring data on the web is important. We're exploring how we could better support this in the future, and [would welcome your input](https://github.com/chanzuckerberg/cellxgene/issues/875)!
-
-In the meantime, you can see examples of how other groups have approached this in our [gallery](gallery). While we don't officially support web deployment, we've offered some guidance below on one way to deploy cellxgene to the web.
-
-## General notes and cautions
-
-Please consider the following when deploying cellxgene in any "hosted" environment, especially where access from the broader Internet is possible:
-
-- Information security requires careful configuration of the host environment, including firewall, logging, etc. Please follow best practices.
-- cellxgene includes features which may be inappropriate for a hosted deployment. You may wish to use the following command line option: `--disable-diffexp`.
-- `cellxgene launch` currently uses Flask's development server, which is not recommended for hosted deployment (see the [Flask documentation](https://flask.palletsprojects.com/en/1.1.x/tutorial/deploy/#run-with-a-production-server))
-- We have no testing or official support for deployments where multiple users are accessing the same cellxgene instance.
-- Your cellxgene instance is likely to hang or crash if too many people access it at the same time, especially if they using functions that call the Python backend (such as differential expression, noted above).
-- cellxgene only supports one instance per dataset
-
-If you believe you have found a security-related issue with cellxgene, please report the issue immediately to
-
-**Note**: automatic opening of the browser with the `--open` flag only works on some platforms (eg, OSX). On other platforms you'll need to directly point to the provided link in your browser.
-
-## Launching from a URL
-
-You can also launch from a URL directly like this:
-
-```
-cellxgene launch https://github.com/chanzuckerberg/cellxgene/blob/main/example-dataset/pbmc3k.h5ad
-```
-
-Support for S3 and GCS is not enabled by default. If you wish to directly access S3 or GFS, install one or both of the following packages:
-
-- [s3fs](https://s3fs.readthedocs.io/en/latest/) for S3 support
-- [gcsfs](https://gcsfs.readthedocs.io/en/latest/) for GCS support
-
-For example:
-
-```
-pip install s3fs
-cellxgene launch s3://mybucket.s3-us-west-2.amazonaws.com/mydata.h5ad
-```
-
-## Options for cellxgene `launch`
-
-**For the most up-to-date and comprehensive list of options, run `cellxgene launch --help`**
-
-`--open` automatically opens the web browser after launching (caveat: only works on some operating systems).
-
-`--disable-annotations`, `--annotations-file` & `--annotations-dir` all have to do with creating new categorical annotations in the application. We have a [whole separate page](annotations) about their usage! :)
-
-`--diffexp-lfc-cutoff` as explained [in the methods](methods), genes are only returned in differential expression if the effect size is above the specified threshold for log fold change. Defaults to 0.01.
-
-`--disable-diffexp` will disable and hide the `Compute Differential Expression` feature.
-For large datasets, or datasets loaded with the `--backed` option, computing differential expression may
-be extremely slow or use excessive resources on the host computer (e.g., memory thrashing).
-Disabling the feature will ensure that this computation is not initiated accidentally.
-
-`--backed` option instructs `cellxgene launch` to read the H5AD file in "backed" mode (for more information, see the
-[anndata.read_h5ad() documentation](https://anndata.readthedocs.io/en/latest/anndata.read_h5ad.html#anndata.read_h5ad)).
-
-By default, cellxgene will read the entire H5AD will be into memory at startup, improving application speed and performance.
-Very large datasets may not fit in memory. The "--backed" mode will read the file incrementally, reducing memory
-use, and for large files, improving startup speed. _However_, this option will also significantly slow
-down access to gene expression histograms, and may render differential expression calculations too slow
-to use (see `--disable-diffexp` for an option to disable this feature).
-
-`--embedding` restricts which embeddings will be available in the viewer. By default, all embeddings specified in `anndata.obsm['X_name']` will be loaded; if you have many embeddings, you may wish to restrict this list for a speedier launch.
-
-`--title` adds a title to the viewer. Defaults to file name.
-
-`--about` adds a link where users can go to find more infomation about the dataset. Requires `https`.
-
-`--obs-names` allows you to specify which column in `anndata.obs` to use as `anndata.obs.index`.
-
-`--var-names` allows you to specify which column in `anndata.var` to use as `anndata.var.index`.
-
-`--max-category-items` omits categorical metadata fields that contain more than N _distinct_ values. Defaults to 1000.
diff --git a/docs/posts/methods.md b/docs/posts/methods.md
deleted file mode 100644
index 22a5407e..00000000
--- a/docs/posts/methods.md
+++ /dev/null
@@ -1,24 +0,0 @@
-# Methods
-
-## Data structure: _anndata_ fields used for visualization
-
-### Expression data
-
-Gene expression values are pulled from `anndata.X`. These feed into the histograms, scatterplot, colorscale, and differential expression calculations. We're [working on ways](https://github.com/chanzuckerberg/cellxgene/issues/689) to incorporate `anndata.raw` and other `anndata.layers`!
-
-### Metadata
-
-Categorical (e.g., cluster labels) and continuous (e.g., pseudotime) metadata are pulled from `anndata.obs`. Any column added here will be available for visualization in cellxgene. You can also [create new categorical annotations](annotations) within the application.
-
-### Embeddings
-
-cellxgene looks for embeddings (e.g., tSNE, UMAP, PCA, spatial coordinates) in `anndata.obsm`. These fields must follow the scanpy convention of starting with `X_`, e.g., `anndata.obsm['X_umap']`. If an embedding has more than two components, the first two will be used for visualization.
-
-## Differential expression
-
-We're actively working on how to improve differential expression within the app.
-**N.B.: the [current implementation](https://github.com/chanzuckerberg/cellxgene/blob/main/server/app/scanpy_engine/diffexp.py#L40) assumes normally distributed values on a linear scale.**
-
-Currently, we use a [Welch's _t_-test](https://en.wikipedia.org/wiki/Welch%27s_t-test), which assumes that the two populations are each normally distributed, but may have unequal variance. We use a two-sided t-test against the null hypothesis that the two populations have **equal** means. P-values are adjusted with the [Bonferroni corrrection](https://en.wikipedia.org/wiki/Bonferroni_correction).
-
-To help avoid spurious results, we use the log fold change to filter genes, retaining those where `|log2( mean(set1) / mean(set2) )| > 0.01`; this threshold can be configured with the [`--diffexp-lfc-cutoff`](launch) command. We then sort genes by their associated `|t value|` and return the top 15 genes.
diff --git a/docs/posts/prepare.md b/docs/posts/prepare.md
deleted file mode 100644
index c7f30d3d..00000000
--- a/docs/posts/prepare.md
+++ /dev/null
@@ -1,131 +0,0 @@
----
-layout: default
-title: prepare
-description: Preparing your data
----
-# Data format requirements
-
-If your data is in `h5ad` file (from the [`anndata`](https://anndata.readthedocs.io/en/latest/index.html) library) and meets the following requirements, you can go straight to `cellxgene launch`:
-
-- Expression values (raw or normalized) in `anndata.X`
-- At least one embedding (e.g., tSNE, UMAP) in `anndata.obsm`, specified with the prefix `X_` (e.g., by default scanpy stores UMAP coordinates in `anndata.obsm['X_umap']`)
-- A unique identifier is required for each cell, which by default will be pulled from the `obs` DataFrame index. If the index is not unique or does not contain the cell ID, an alternative column can be specified with `--obs-names`
-- A unique identifier is required for each gene, which by default will be pulled from the `var` DataFrame index. If the index is not unique or does not contain the gene ID, an alternative column can be specified with `--var-names`
-
-#### What about R objects from seurat / bioconductor!?
-We hear you! We'd also love to be able to ingest these files directly. This isn't currently possible, but in the meantime, you can use [sceasy](https://bioconda.github.io/recipes/r-sceasy/README.html) ([docs](https://cellgeni.readthedocs.io/en/latest/visualisations.html)) to convert to `h5ad`. Seurat also has some [handy conversion tools](https://satijalab.org/seurat/v3.0/conversion_vignette.html) that you can try out.
-
-#### Can I use data hosted on the web somewhere?
-Yes! You can launch from a URL instead of a filepath. The same data format requirements apply. Please see [here](launch) for more details.
-
-# Data format options
-
-#### Category colors
-`cellxgene` will display [scanpy-style color
-information](https://github.com/chanzuckerberg/cellxgene/issues/1152#issue-564361541)
-for category-label pairs. An example of this format is shown below:
-
-```
->>> category = "louvain"
->>> # colors stored in adata.uns must be matplotlib-compatible color information
->>> adata.uns[f"{category}_colors"]
-array(['#1f77b4', '#ff7f0e', '#2ca02c', '#d62728', '#9467bd', '#8c564b', '#e377c2', '#bcbd22'], dtype='